[AI Data Center Security] “Availability-First Security: 4 IEC 62443 Lessons for AI Training Clusters”


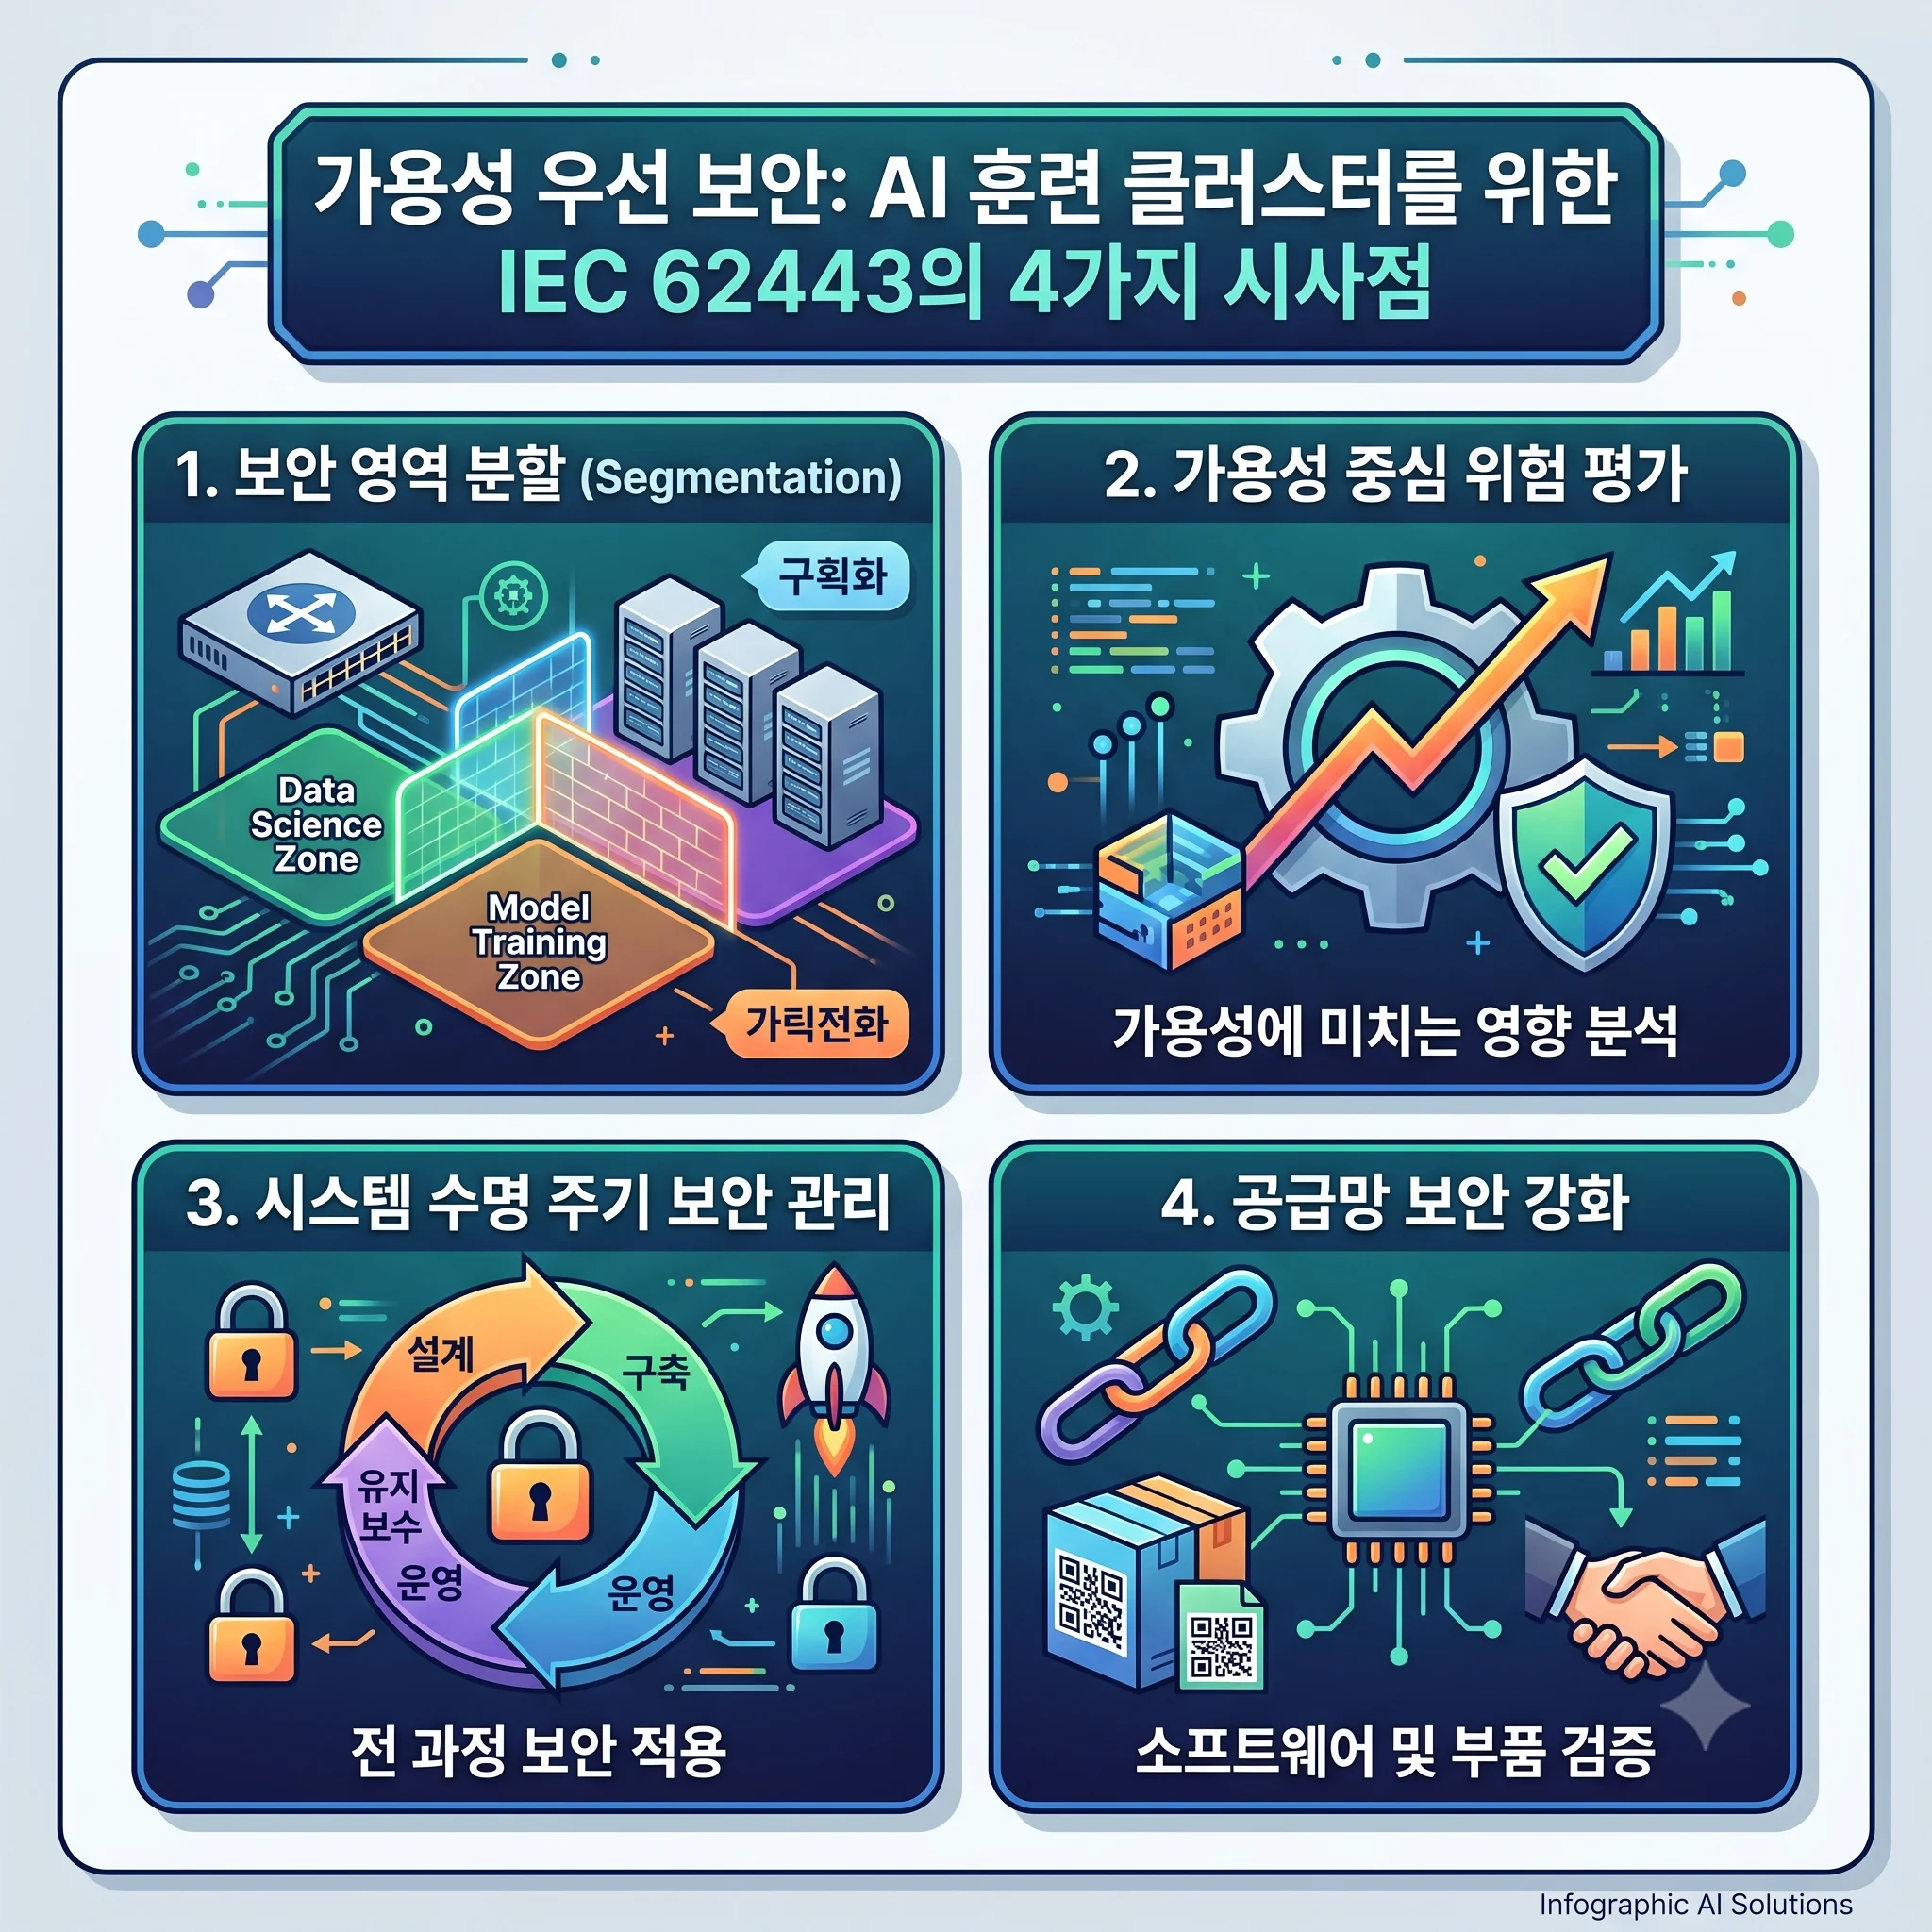
Availability-First Security: 4 IEC 62443 Lessons for AI Training Clusters
By Jin Ho Kang · OT/ICS Security Consultant
Table of Contents
- Why AI Training Clusters Need Availability-First Security, Not the Standard IT Playbook
- IEC 62443’s Seventh Foundational Requirement: Availability-First Security by Design
- What My Own Research Found: IT-Centric Controls Have a Negative Effect on Availability
- Applying FR7 Thinking to GPU Clusters: Degraded Mode, Not Full Stop
- The Cost of Getting the Tradeoff Wrong
- Bringing It Together
- References
Manufacturing security engineers learned a rule the hard way, decades before anyone was training a language model: a security control that takes a production line down is not a security improvement, it is a new failure mode wearing a compliance badge. That rule has a name in the ISA/IEC 62443 standard — resource availability — and it is the reason OT security has always looked different from IT security. AI training clusters are now running into the exact same wall. When a single multi-week training run represents millions of dollars in GPU-hours, availability-first security stops being a nice philosophical stance and becomes the only approach that survives contact with the economics of the workload. Having spent years applying IEC 62443’s availability-first security principles to manufacturing plants — and having built my own doctoral research around exactly this tradeoff — I think this is the single most transferable lesson OT security has to offer AI infrastructure teams.
Why AI Training Clusters Need Availability-First Security, Not the Standard IT Playbook
The scale of modern training runs makes availability fragile even before security enters the picture. Meta’s own published account of training Llama 3 on a 16,384-GPU H100 cluster over 54 days recorded 466 job interruptions — 47 planned and 419 unexpected — with roughly 78% of the unexpected interruptions traced to confirmed or suspected hardware issues, and GPU-related problems alone accounting for 58.7% of them (Meta AI, “The Llama 3 Herd of Models,” 2024). Despite that volume of failures, the team still achieved above 90% effective training time only by treating fast detection and fast recovery as first-class engineering problems, not afterthoughts. At that scale, research modeling the mean time to failure of a job running across the full cluster puts it at roughly 2.7 hours, compared with about 7.9 hours for a 1,024-GPU job (TrainMover, 2024, citing Meta’s own operational data). This is the baseline reality an availability-first security program has to work inside: a system that is already spending a meaningful share of its runtime recovering from failure has no slack left to absorb a security control that adds its own downtime on top — which is precisely the scenario availability-first security exists to prevent.
IEC 62443’s Seventh Foundational Requirement: Availability-First Security by Design
IEC 62443-3-3 organizes its technical requirements into seven foundational requirement (FR) families, and the seventh — Resource Availability — is where the standard’s availability-first security philosophy is written down explicitly rather than implied (Fortinet; UpGuard, 2025). FR7 breaks into eight system requirements: denial-of- service protection (SR 7.1), which requires the system to enter a predetermined degraded mode rather than fail outright under attack; resource management (SR 7.2), which prevents any single process — security tooling included — from exhausting shared compute or memory; control system backup (SR 7.3) and recovery (SR 7.4), which require backups to be integrity-protected without corrupting the live system in the process; and continuity requirements covering emergency power and least-functionality configuration (UpGuard, 2025). Read as a whole, FR7 is not a checklist bolted onto a security program — it is availability-first security codified as eight specific, testable engineering requirements, and it exists because the drafters of IEC 62443 assumed, correctly, that a control which cannot survive contact with an availability-critical system will eventually be disabled by the people running that system anyway.
Fig. 1 — IEC 62443-3-3 FR7 (Resource Availability): the 8 system requirements behind availability-first security
What My Own Research Found: IT-Centric Controls Have a Negative Effect on Availability
This is not just standards language to me — it is the central finding of my own doctoral research on OT security control prioritization in manufacturing environments. Using a multiple regression model built on a 100-respondent expert survey across a 39-control, 13-item integrated framework drawn from ISO/IEC 27001, IEC 62443-3-3, and NIST CSF, the analysis found a statistically negative relationship between the intensity of IT-centric security controls and manufacturing availability outcomes. In plain terms: the more a security program imported IT’s default assumptions — frequent patch cycles, continuous endpoint scanning, generic access-review cadences — without adapting them to an availability-first security model, the more it measurably degraded the operational uptime it was supposed to protect. That is not an argument against securing OT or AI systems; it is an argument for recognizing that the same control, implemented with IT-style defaults instead of availability-first security engineering, can flip from a net benefit to a net cost. AI infrastructure teams evaluating security tooling for GPU clusters are facing the identical decision, usually without the benefit of an availability-first security regression line to check their assumptions against.
Fig. 2 — The tradeoff behind availability-first security: control intensity vs. measured availability impact
Applying FR7 Thinking to GPU Clusters: Degraded Mode, Not Full Stop
Translating FR7 into GPU cluster terms produces a concrete, availability-first security design pattern rather than an abstract principle. SR 7.1’s predetermined degraded mode becomes a rule that a detected anomaly on the training fabric triggers a controlled checkpoint-and-pause sequence, not an abrupt network-level kill switch that destroys an in-flight collective operation across thousands of GPUs — the same graceful-degradation logic that availability-first security requires of any industrial control system. SR 7.2’s resource management becomes a hard constraint that security agents running on training nodes are budgeted a fixed, small share of host CPU and memory, so that endpoint monitoring can never contend with the data-loader threads or NCCL processes that determine whether the fabric stays synchronized. SR 7.3 and 7.4 map directly onto checkpoint integrity: a security-driven backup or snapshot process must never touch the same storage bandwidth a training job is using to write its own checkpoints, because on a system where checkpoint write speed is already a bottleneck, competing for that bandwidth is functionally a denial-of-service event the standard explicitly warns against. And SR 7.7’s least-functionality principle argues for the thinnest possible security footprint on nodes that sit inside the training fabric zone, with the heavier inspection and logging pushed to the orchestration and enterprise boundaries instead — precisely where OpenAI’s own data center security postings describe compensating controls for operational constraints in OT-adjacent networking environments as a named job requirement.
The Cost of Getting the Tradeoff Wrong
The economics make the case bluntly. Meta’s earlier OPT-175B run on 992 A100 GPUs took about 57 days against an estimated 25-day ideal, meaning roughly 56% of total run time was consumed by failure handling rather than useful training (survey cited in “Efficient Training of Large Language Models on Distributed Infrastructures,” 2024). Independent analysis of Meta’s Llama 3.1 405B run estimates checkpointing and recovery overhead at around 2.1% of total training time even under a well-optimized configuration, and shows that overhead climbing sharply enough at extreme scale to eventually make training infeasible if left unmanaged (Epoch AI, 2025). On the operational side, Amazon’s own SageMaker HyperPod documentation reports that replacing a single failed instance in a 256-instance cluster takes roughly 940 seconds, and resuming the full training job afterward takes about 2,390 seconds — costs that are paid in idle GPU-hours regardless of whether the interruption came from a hardware fault or an overzealous security control (AWS, 2025). None of these numbers include security overhead; they describe the availability margin AI infrastructure teams are already spending down before a single firewall rule or endpoint agent gets added. Availability-first security is what keeps that margin from collapsing further.
Fig. 3 — The availability-first security margin: what training runs already spend before security is added
Bringing It Together
IEC 62443’s FR7 was written for programmable logic controllers, not GPU fabrics, and no one should expect its literal text to transfer unmodified. But the discipline behind it — degrade gracefully instead of failing hard, budget your own resource footprint, never let a backup process compete with the workload it is protecting — is availability-first security in its most portable form, and it maps onto AI training infrastructure almost line for line. My own dissertation research suggests the risk of skipping this discipline is not theoretical: security controls built on IT-centric defaults measurably reduced availability in the manufacturing environments I studied, and there is no reason to expect GPU clusters, which are considerably less forgiving of downtime, to be an exception. For anyone securing AI compute infrastructure, availability-first security is not a constraint on the job — it is the job.
References
- Meta AI, “The Llama 3 Herd of Models” (2024)
- TrainMover: An Interruption-Resilient Runtime for ML Training (2024)
- Fortinet, “IEC 62443 Standard: Industrial Cybersecurity Framework Explained”
- UpGuard, “What is IEC/ISA 62443-3-3:2013?” (2025)
- Epoch AI, “Hardware Failures Won’t Limit AI Scaling” (2025)
- “Efficient Training of Large Language Models on Distributed Infrastructures: A Survey” (2024)
- AWS, “Reduce ML Training Costs with Amazon SageMaker HyperPod” (2025)


